Poking at LLM benchmarks, 1 - Automation Bench
First of a few posts looking at benchmarks uses to evaluate LLMs. Each new model release decimates the older benchmarks but outside models from the Openai/Anthropic duopoly and Deepseek, I still don't find the others reliable enough to be a daily driver. Would be interesting to see which benchmarks are actually a good proxy for things I use the models for (mostly interactive coding, no software factories).
I want to pick benchmarks that aren't saturated and yet something smaller models can make a reasonable pass at. The plan is to run a handful of tasks from each with a cheap model, read the trajectories, and see how the models go about solving them.
- Haven't got the budget for wasteful runs with frontier models, and the non open source ones don't expose thinking traces either which defeats the whole purpose (yep, I know chain-of-thought isn't causal).
- Additionally, benchmarks like Terminal bench also require a lot of background knowledge, which smaller models aren't going to be great at.
Newer model releases (Claude Fable, GPT Astra) reported scores on AutomationBench - a benchmark created by Zapier, which focuses on business process workflows. It includes tasks like, reconciling excel transactions, setting up onboarding for new hires, and a lot more akin to digital paperwork.
Feels like a good fit for our objective:
- External knowledge required is limited to knowing the popular software services, and useful know-how for the task lives in the environment. The model just has to find it, and string together tool calls with some judgement. That's trainable for small models.
- Frontier models still sit below 50% accuracy on it, so there's headroom to improve.
How AutomationBench tasks were constructed
The arxiv paper covers the shape of the benchmark:
- The public task-set has 600 entries across different domains (support, financial, etc.), plus a list of 200 simple tasks.
- Completing a task requires the use of multiple (simulated) SaaS apps, out of a total of 47 (Google drive, Salesforce, Buffer, etc.). Each app provides a set of tools the agent can call.
- Each task specifies a list of assertions against which the final state is checked, with a strict pass/fail on each.
The tasks are LLM-generated (Opus 4.6, GPT 5.3 Codex, Gemini 3) by mining Zapier's usage data, and then "hardened" by adding decoy data entries with similar names, obscuring key information and having strict policy rules. Only a sub-sample of the tasks underwent manual inspection.
NOTE: The leaderboard on Zapier's website evaluates models on a held-out private task set, which was created with "similar distribution and assertion framework, purposely harder".
Evaluation can be run in one of three modes.
-
api: raw REST schemas behind search + execute tool -
zapier: same but nicer action scehmas, regular python methods. -
limited_zapier: only the exact tools specified for a task are made available to it -
Three toolsets.
api= raw REST schemas behind search+execute,zapier= same but Zapier's nicer action schemas,limited_zapier= only the exact tools the task needs, no search. I ranzapiersince that's the honest setting - nobody hands you the 4 tools you need in real life. -
Public vs private: leaderboard scores are on a held-out private set, "similar distribution and assertion framework, purposely harder". Same generator, same helper library, same hardening. Keep that in mind for the next section.
What I found
Setup: zapier toolset, inkling-small via OpenRouter, ~10 tasks across finance / sales / marketing / HR, every trace read by hand. Concrete bugs filed as zapier/AutomationBench#24.
Score: 6 or 7 of 10 tasks had something that either makes the task unsolvable or lets a wrong answer through.
The guard that doesn't guard (finance.subscription_billing)
- Task: billing must not touch the Ridgeway row in the subscriptions sheet. Rubric enforces this with
google_sheets_row_not_updated, which is literallynot row_updated(...), androw_updatedchecks a flag set on edit. - Delete the row: flag never set, row gone,
row_updated→ False,not_updated→ True. Guard passes. - Inkling did exactly this. Deleted Ridgeway, recreated it with a new renewal value, assertion meant to catch that waved it through.
- Shared helper, so this isn't a one-task bug.
Tool errors that look like data (marketing.ad_performance_review)
- Model called
gmail_send_emaildirectly instead of passing it toexecute_tool. Env catches every exception and returnsstr(e)as the tool result. For a KeyError that's the quoted key. Model got back'gmail_send_email', read it as a success, moved on. - No error marker at all. Should be
{"error": ..., "message": ...}. - A strong model never makes the original mistake, so nobody saw this.
The date that doesn't exist (finance.late_fee_calculation)
- Late fees depend on days overdue. Expected amounts in the rubric are computed from
meta.current_time. The model never sees it, and there's no clock tool. - Inkling guessed a date from an email in the inbox, computed a different fee, failed. A perfect model fails too unless it guesses the same date.
Just wrong (sales.recency_selection)
- Prompt: record the source message id for the phone number you pick. Correct source is
msg_marcus_004, assertion 3 checks for it. Assertion 5 also requiresmsg_marcus_003in the note - the older, wrong one. Should be a not-exists. - Typo-class. How many of these in 600 tasks? I don't have a scalable way to find them other than reading traces.
Unsolvable under an evaluation mode (hr.multi_app_new_hire_setup)
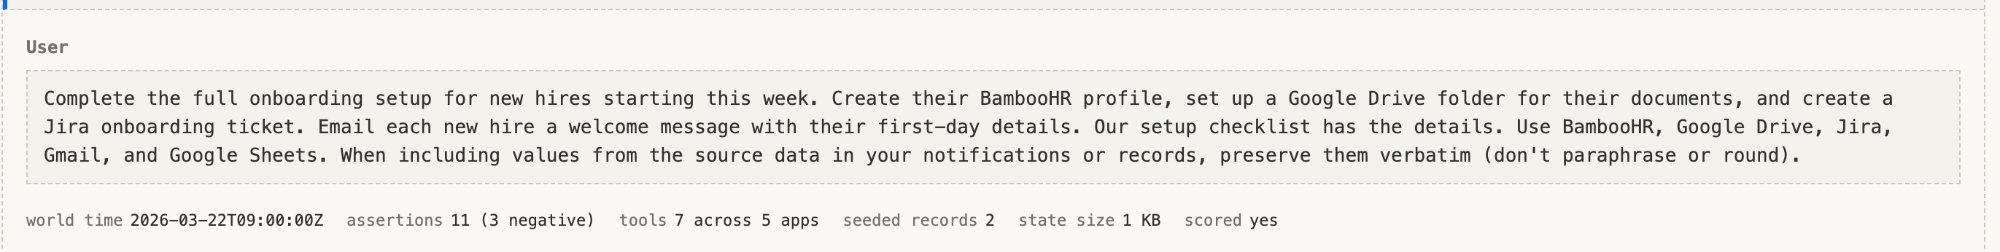
The prompt refers to a setup checklist to find the task steps, without naming the file. The data lives in a Google sheets spreadsheet. However, in the limited_zapier mode, the list of tools specified doesn't include any tools that let you search over files based on their name/contents. So, the model can only invent names and try to see if they exist.
Prompts with no context (marketing.video_repurpose, late_fee_calculation)
- Not a bug, a design complaint. Prompts read like a one-liner from a manager, zero context about how the company works. A real ops person knows holidays live in google calendar not notion, that the content queue is a sheet and not Buffer.j
- Inkling wrote the repurposed posts to Buffer, because Buffer has an "add to queue" action and the model was searching over all tools. Reasonable. Failed, the rubric wanted a sheet row.
- Either give the prompt a "what lives where" blurb, or accept either outcome. Right now it's testing whether the model guesses the task author's tool preference.
Tools vs data (subscription_billing)
- Also not a bug. Inkling searched tools for "google sheets", then for "subscriptions" and "renewals" - those are data, not tools. Search+execute over 500 schemas is a hard interface for a small model and it's a confusion I'd expect to see a lot of. Not sure a fix belongs in the benchmark though.
Fine
- finance.xero_transactions_reconcile. Rubric ok, task ok. Doesn't test the KB policy notes, so weaker than it could be, fair enough.
- subscription_billing has a policy note contradicting the prompt (says don't delete rows). Good thing to check - who does the model listen to.
Thoughts
- I filed a Github issue in the benchmark repo.
- Evaluate an eval with a weak model. Every bug above was invisible in a strong model's trace and obvious in Inkling's. Strong model guesses the right date, never calls the wrong tool name, never deletes the row. Validating with the frontier model only tells you the happy path passes, not that the rubric jdiscriminates.
- Public set bugs don't directly say anything about the private leaderboard. But same generator, same shared assertion helpers, same sampled-not-exhaustive review. I'd assume the same bug rate. And the errors go both ways - bug 1 passes wrong answers, bugs 3/4/5 fail right ones - so I can't even say which direction the leaderboard is off.
- This is what "LLM generated, human sampled" buys you. Not a knock, 600 tasks x 47 apps is real work and the bones are good. But validation has to be adversarial - run a bad model, read every failure, confirm it's the model's fault. Their RLVR pressure test is the right instinct, it just needed to keep going.
- For training a small model on this, the public set is usable after fixing / filtering. Probably the next post.